Self-Hosted Meilisearch for Multiple Projects: One Instance, Scoped Keys, Zero Leaks
Most tutorials quietly assume one search server per app. That's fine at work. On a personal VPS running four projects, it means four copies of the same engine eating RAM, four things to update, and four places to forget a backup.
I run one self-hosted Meilisearch for all my projects instead. My portfolio's blog search and its admin dashboard both use it, and other projects can join without being able to read a single document that isn't theirs. This post is the exact setup: the Docker service, the naming rule, the scoped API keys and the proxy that makes it safe to expose to browsers.
What's inside
- Why share one instance at all?
- The architecture in one picture
- Running Meilisearch with Docker
- Rule 1: prefix every index
- Rule 2: scoped API keys per project
- Rule 3: a public proxy that only allows search
- Limits, snapshots and health checks
- Wiring it into a backend
- Common mistakes
- FAQ
1. Why share one instance at all?
Meilisearch is fast, light and simple to run, but each instance still reserves memory for its indexes and needs updating and backing up.
Sharing one instance gives you:
- Less RAM on a small VPS: one process instead of several.
- One thing to upgrade, monitor and back up.
- The same search experience across projects, with the same tuning knowledge.
The risk is obvious: one project reading or deleting another's data. The three rules below remove that risk.
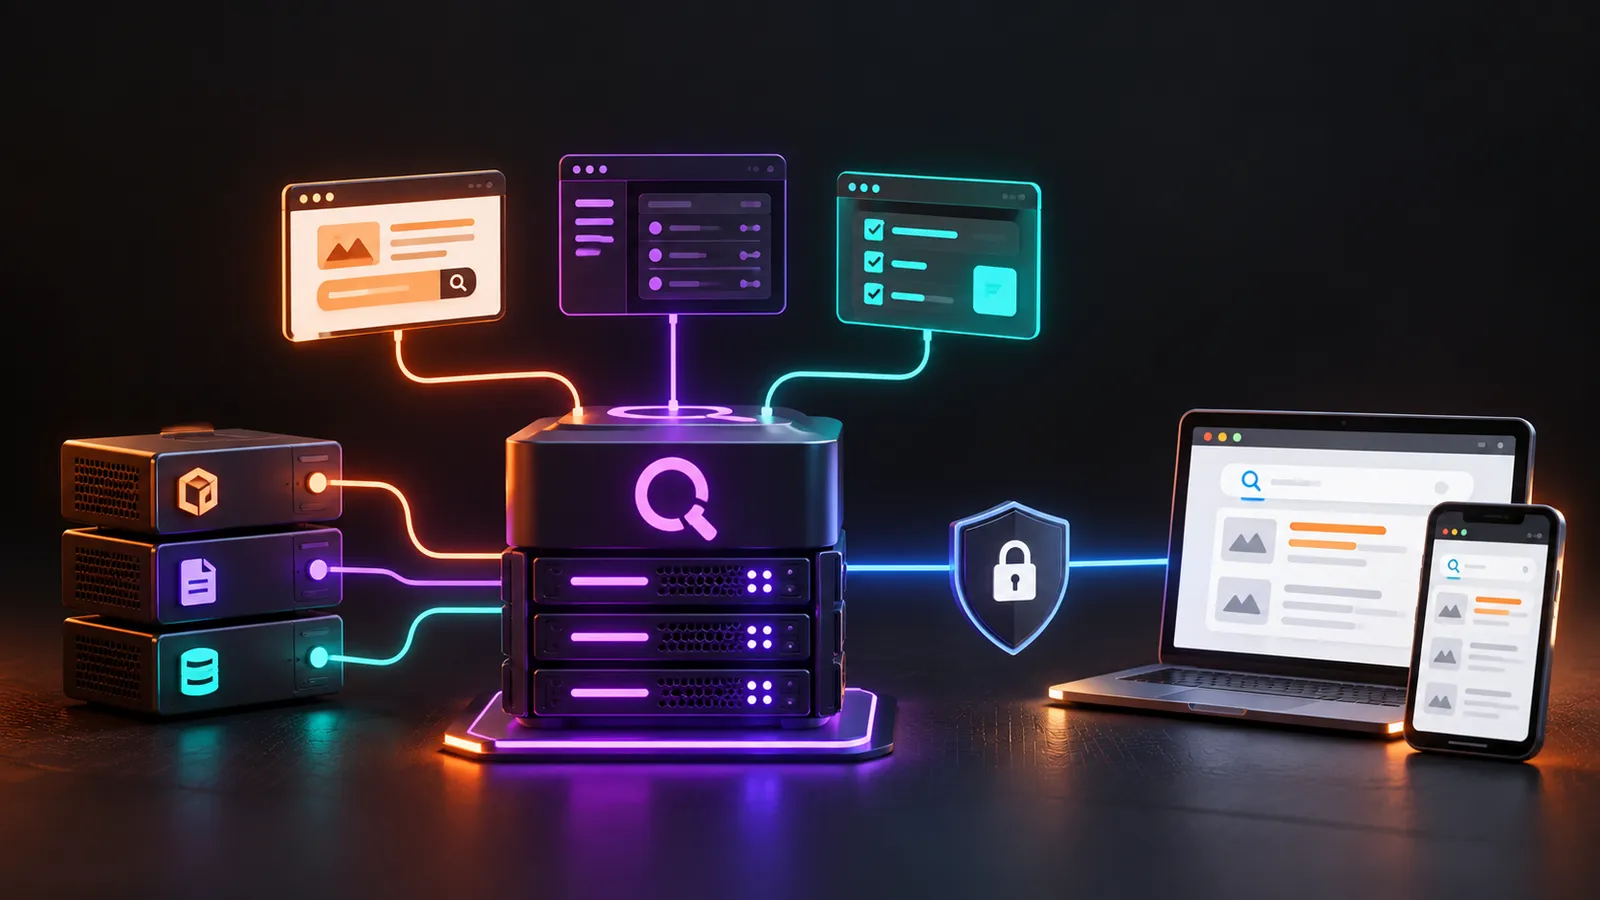
2. The architecture in one picture
- Meilisearch runs on an internal Docker network with no ports published on the host.
- Each backend writes over that internal network with its own admin key, limited to its own indexes.
- Browsers search through a public subdomain, via the reverse proxy, using a search-only key limited to public indexes.
- The master key lives only in the server's
.envfile and is used to create the other keys.
On my server, Meilisearch sits on the same Docker network as the apps Dokploy deploys, so backends reach it at http://meilisearch:7700. If you're choosing a platform for that part, see Dokploy vs Coolify vs CapRover.
3. Running Meilisearch with Docker
A minimal Compose file:
services:
  meilisearch:
    image: getmeili/meilisearch:v1.x.y   # pin an exact version
    restart: unless-stopped
    environment:
      MEILI_ENV: production
      MEILI_MASTER_KEY: ${MEILI_MASTER_KEY}
      MEILI_NO_ANALYTICS: "true"
      MEILI_MAX_INDEXING_THREADS: "1"
      MEILI_SCHEDULE_SNAPSHOT: "86400"   # daily snapshot, in seconds
    volumes:
      - ./data:/meili_data
    networks:
      - apps
    deploy:
      resources:
        limits:
          memory: 768M
          cpus: "1.0"

networks:
  apps:
    external: true
Key points:
- Pin the image version. Meilisearch upgrades can change the on-disk format, so upgrade on purpose, with a snapshot or dump taken first.
MEILI_ENV: productionrequires a master key and turns off the built-in search preview.- No
ports:section. Nothing on the internet can reach it directly. - Generate the master key with something like
openssl rand -base64 48and keep it only in.env(and your password manager).
4. Rule 1: prefix every index
Give every index a project prefix:
portfolio_blogportfolio_admintaskflow_tasks
This looks like a naming convention, but it's what makes key scoping work. Meilisearch API keys can be limited to index patterns like portfolio_*, so the prefix becomes the security boundary.
Decide the rule before any project writes data. Renaming indexes later means reindexing.
5. Rule 2: scoped API keys per project
The master key can do everything, including create and delete keys. It should never be in an application's config.
For each project, create two keys with the master key:
1. Admin key for the project's backend: can add documents, change settings and delete indexes, but only within its own prefix.
curl -X POST "http://meilisearch:7700/keys" \
  -H "Authorization: Bearer $MEILI_MASTER_KEY" \
  -H "Content-Type: application/json" \
  --data '{
    "name": "portfolio-admin",
    "actions": ["documents.*", "indexes.*", "settings.*", "tasks.get", "search"],
    "indexes": ["portfolio_*"],
    "expiresAt": null
  }'
2. Search key for the browser: can only search, and only the indexes that are meant to be public.
curl -X POST "http://meilisearch:7700/keys" \
  -H "Authorization: Bearer $MEILI_MASTER_KEY" \
  -H "Content-Type: application/json" \
  --data '{
    "name": "portfolio-search",
    "actions": ["search"],
    "indexes": ["portfolio_blog"],
    "expiresAt": null
  }'
Notice the search key lists portfolio_blog only, not portfolio_*. My admin dashboard has its own private index (portfolio_admin) holding drafts and leads. If the public key used the wildcard, anyone with it could search that private index. I tightened exactly this on my own setup.
I wrap both calls in a small script, create-project-keys.sh <project>, that writes the keys to a per-project env file. Adding a new project takes one command.
6. Rule 3: a public proxy that only allows search
Even with scoped keys, I don't want the full Meilisearch API reachable from the internet. The reverse proxy only routes these paths to it:
/health/multi-search/indexes/<name>/search
Everything else returns 404: key management, document writes, settings, tasks and dumps. I also rate-limit search (about 20 requests per second per IP) so a scraper can't hammer it.
With Traefik, that's a router with a path rule like this:
rule: >
  Host(`search.example.com`) &&
  (Path(`/health`) || Path(`/multi-search`) || PathRegexp(`^/indexes/[a-z0-9_]+/search$`))
In my case, the browser actually calls my API, which then calls Meilisearch, because the site's Content Security Policy only allows requests to the API's domain. That's even tighter: the search key never reaches the browser. Use the public route when you need direct browser search, for example for instant search as you type on a static site.
7. Limits, snapshots and health checks
On a shared VPS, search shouldn't be able to starve everything else:
- Memory and CPU caps (768 MB and one CPU in my setup) keep a large reindex from pushing other containers into swap.
MEILI_MAX_INDEXING_THREADS: 1makes indexing slower but gentler.- A daily snapshot gives you a quick restore point. Copy snapshots off the server too. A snapshot on the same disk isn't a backup.
- A status script that calls
/healthand lists indexes and document counts, without printing any keys, so it's safe to run in front of anyone.
8. Wiring it into a backend
My ASP.NET Core backend keeps the search index in sync automatically:
- On startup, a background worker reindexes everything (cheap at blog scale).
- On publish, edit or delete, a domain event updates just that document.
- Every 15 minutes, a safety-net resync catches anything missed.
- If Meilisearch is down, the search endpoint returns a clear
503and the frontend falls back to a simple local search over the post list, so the site never shows a broken search box.
The backend reads two settings, the base URL (http://meilisearch:7700) and its project's admin key, both from environment variables. Never from Git. If you're unsure where those should live, I wrote about it in Where should your secrets live?
9. Common mistakes
- Putting the master key in an app. If that app leaks its config, every project's data is exposed.
- Wildcard search keys.
portfolio_*on a public key also covers your private indexes. - Publishing port 7700. Keep it on the internal network and route only what you need.
- Unpinned
latestimage. An automatic upgrade can refuse to open your existing data. - No memory limit. One bulk import can slow every other app on the box.
- Trusting snapshots on the same disk. Copy them elsewhere, as I explain in Blob storage 101.
FAQ
Is Meilisearch multi-tenant?
Not with separate databases per tenant, but scoped API keys limited by index pattern (and tenant tokens for per-user filtering) give you strong isolation in practice. For sensitive multi-customer data at scale, separate instances are still the safer choice.
How much RAM does Meilisearch need?
For a few thousand documents, very little: a couple of hundred MB is typical. It uses memory-mapped files, so give it headroom for larger datasets and set a cap so it can't take everything.
Meilisearch vs Algolia vs Elasticsearch?
Algolia is hosted and excellent, but priced by usage. Elasticsearch is powerful but heavy to run. Meilisearch sits in the sweet spot for small teams: typo-tolerant instant search, simple to operate, free to self-host.
Can I use tenant tokens instead of separate keys?
Yes. Tenant tokens are signed with a parent API key and add search rules, like filters per user. They're great for "users only see their own records". Per-project keys still make sense as the outer boundary.
How do I upgrade safely?
Create a dump, pin the new version, start it with the dump import, check index counts, then remove the old data. Never jump versions on a live instance without a dump.
Need search on your site?
Fast, typo-tolerant search is something I build into the web apps I make, self-hosted so there is no per-search bill. If you want it on your site, or a second opinion on your setup, I'm happy to help.
More from the blog
More on the same themes as this post.
Dokploy vs Coolify vs CapRover: Which Self-Hosted PaaS Should You Run in 2026?
How I Built a WhatsApp AI Chatbot Without the Official API (and Kept the Number From Getting Banned)